AI hardware guide

The AI hardware landscape, at a glance.

Today’s AI accelerators side by side: how much model each one holds, how fast it answers one person, how many people it can serve at once — alone and grouped — and whether it belongs in a rack, under a desk or on it.

40accelerators & systems
6classes
8Kcontext per user
≥15tok/s per user

// specs from each vendor’s datasheet · speeds are estimates from a stated model · see “How we estimate”

How to read a card

Seven indicators, the same on every card.

Power

Maximum board power (or system power for desktops). The bar is on a log scale up to 1,400 W.

Fits

Where it is built to run: Rack (server airflow), Tower (workstation), Desktop (a self-contained box).

Precision

The lowest number format the silicon accelerates. FP4 and FP8 roughly halve and quarter the memory a model needs compared with FP16.

Model tags

The size class that fits one device, and what a typical group of them holds.

Typical TPS

Tokens per second for ONE user on the model shown — how fast an answer appears (a word is about 1.3 tokens).

Users

How many people can chat at once, each still getting ≥15 tokens/s, with an 8K-token context each.

Runs

Popular open models that fit one device with room left for conversations.

Data-centre flagships

HBM memory and NVLink — built for 8-accelerator baseboards and high-density racks.

B300 (Blackwell Ultra)
Blackwell Ultra

B300 (Blackwell Ultra)

288 GB HBM3e · 8.00 TB/s

Power
1,100 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
397B MoE8× → 1T MoE
Typical TPS
≈ 300 tok/sQwen3.5 122B-A10B · FP4 · one user
Users
≈ 380–640at ≥15 tok/s each
Runs
GLM-4.7DeepSeek-V4-FlashQwen3.5 122B-A10Bgpt-oss-120bALLaM 7B

Interconnect: NVLink 5 · 1.8 TB/sCooling: Air or liquid (baseboard)

8× grouped · 8-GPU baseboard · NVLink · Kimi K2.6 · ≈ 200 tok/s · ≈ 3,100–5,100

Per GPU on an 8-GPU HGX baseboard: about 1,100 W in shipping HGX systems, up to 1,400 W in NVIDIA’s maximum configuration.

Sources: 1 · 2 · 3

B200
Blackwell

B200

180 GB HBM3e · 8.00 TB/s

Power
1,000 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
284B MoE8× → 1T MoE
Typical TPS
≈ 300 tok/sQwen3.5 122B-A10B · FP4 · one user
Users
≈ 380–640at ≥15 tok/s each
Runs
Qwen3.5 122B-A10Bgpt-oss-120bMistral Small 4Jais 2 70BALLaM 7B

Interconnect: NVLink 5 · 1.8 TB/sCooling: Air or liquid (baseboard)

8× grouped · 8-GPU baseboard · NVLink · Kimi K2.6 · ≈ 200 tok/s · ≈ 1,900–3,200

Ships with 180 GB per GPU in HGX B200 (192 GB was the launch figure).

Sources: 1 · 2 · 3

B100
Blackwell

B100

192 GB HBM3e · 8.00 TB/s

Power
700 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
284B MoE8× → 1T MoE
Typical TPS
≈ 300 tok/sQwen3.5 122B-A10B · FP4 · one user
Users
≈ 380–640at ≥15 tok/s each
Runs
Qwen3.5 122B-A10Bgpt-oss-120bMistral Small 4Jais 2 70BALLaM 7B

Interconnect: NVLink 5 · 1.8 TB/sCooling: Passive — needs server airflow

8× grouped · 8-GPU baseboard · NVLink · Kimi K2.6 · ≈ 200 tok/s · ≈ 2,200–3,600

Announced in 2024 as a 700 W drop-in for H100 baseboards; shipped only in small volumes before B200 replaced it. Figures from launch materials.

Sources: 1 · 2

H200 SXM
Hopper

H200 SXM

141 GB HBM3e · 4.80 TB/s

Power
700 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
122B MoE8× → 1T MoE
Typical TPS
≈ 310 tok/sgpt-oss-120b · FP8 · one user
Users
≈ 310–520at ≥15 tok/s each
Runs
gpt-oss-120bJais 2 70BQwen3.6 35B-A3BGemma 4 31BALLaM 7B

Interconnect: NVLink 4 · 900 GB/sCooling: Air or liquid (baseboard)

8× grouped · 8-GPU baseboard · NVLink · Kimi K2.6 · ≈ 190 tok/s · ≈ 1,200–2,000

Sources: 1

H200 NVL
Hopper

H200 NVL

141 GB HBM3e · 4.80 TB/s

Power
600 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
122B MoE4× → 397B MoE
Typical TPS
≈ 310 tok/sgpt-oss-120b · FP8 · one user
Users
≈ 310–520at ≥15 tok/s each
Runs
gpt-oss-120bJais 2 70BQwen3.6 35B-A3BGemma 4 31BALLaM 7B

Interconnect: NVLink bridge (2- or 4-way) · 900 GB/sCooling: Passive — needs server airflow

4× grouped · 4-way NVLink bridge · Qwen3.5 397B-A17B · ≈ 170 tok/s · ≈ 510–840

Sources: 1 · 2

H100 SXM
Hopper

H100 SXM

80 GB HBM3 · 3.35 TB/s

Power
700 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
117B MoE8× → 397B MoE
Typical TPS
≈ 280 tok/sQwen3.6 35B-A3B · FP8 · one user
Users
≈ 340–560at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: NVLink 4 · 900 GB/sCooling: Air or liquid (baseboard)

8× grouped · 8-GPU baseboard · NVLink · Qwen3.5 397B-A17B · ≈ 180 tok/s · ≈ 820–1,400

Sources: 1

H100 NVL
Hopper

H100 NVL

94 GB HBM3 · 3.94 TB/s

Power
400 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
117B MoE4× → 122B MoE
Typical TPS
≈ 290 tok/sgpt-oss-120b · FP8 · one user
Users
≈ 97–160at ≥15 tok/s each
Runs
gpt-oss-120bQwen3.6 35B-A3BGemma 4 31BALLaM 7B

Interconnect: NVLink bridge (pair) · 600 GB/sCooling: Passive — needs server airflow

4× grouped · 4 cards · NVLink pairs · Qwen3.5 122B-A10B · ≈ 180 tok/s · ≈ 1,300–2,200

Sources: 1 · 2

H100 PCIe
Hopper

H100 PCIe

80 GB HBM2e · 2.00 TB/s

Power
350 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
117B MoE4× → 122B MoE
Typical TPS
≈ 230 tok/sQwen3.6 35B-A3B · FP8 · one user
Users
≈ 340–560at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: NVLink bridge (pair) · 600 GB/sCooling: Passive — needs server airflow

4× grouped · 4 cards · NVLink pairs · Qwen3.5 122B-A10B · ≈ 150 tok/s · ≈ 1,000–1,700

Displaced by H100 NVL and H200 NVL on NVIDIA’s current pages.

Sources: 1

A100 PCIe (A800 80GB)
AmpereA100 PCIe shown — same design

A800 80GB

80 GB HBM2e · 1.94 TB/s

Power
300 W
Fits
RackTowerDesktop
Precision
INT8 · FP16
Model tags
122B MoE4× → 397B MoE
Typical TPS
≈ 33 tok/sJais 2 70B · 4-bit · one user
Users
≈ 19–31at ≥15 tok/s each
Runs
Jais 2 70BQwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: NVLink bridge (pair) · 400 GB/sCooling: Passive — needs server airflow

4× grouped · 4 cards · NVLink pairs · Qwen3.5 397B-A17B · ≈ 150 tok/s · ≈ 170–280

A market-specific A100 variant (NVLink 400 GB/s). Also an SXM module on HGX A800 boards at 2.0 TB/s and 400 W. Now effectively end-of-life.

Sources: 1 · 2

Data-centre PCIe cards

Passive or compact cards for standard servers — inference, vision and graphics at scale.

L40S
Ada Lovelace

L40S

48 GB GDDR6 ECC · 0.86 TB/s

Power
350 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
≤ 70B8× → 397B MoE
Typical TPS
≈ 210 tok/sQwen3.6 35B-A3B · 4-bit · one user
Users
≈ 220–360at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Passive — needs server airflow

8× grouped · 8 cards in one server · PCIe · Qwen3.5 397B-A17B · ≈ 110 tok/s · ≈ 54–90

Sources: 1

L40
Ada Lovelace

L40

48 GB GDDR6 ECC · 0.86 TB/s

Power
300 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
≤ 70B8× → 397B MoE
Typical TPS
≈ 210 tok/sQwen3.6 35B-A3B · 4-bit · one user
Users
≈ 220–360at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Passive — needs server airflow

8× grouped · 8 cards in one server · PCIe · Qwen3.5 397B-A17B · ≈ 110 tok/s · ≈ 54–90

Sources: 1 · 2

L40S (L20)
Ada LovelaceL40S shown — same design

L20

48 GB GDDR6 · 0.86 TB/s

Power
275 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
≤ 70B8× → 397B MoE
Typical TPS
≈ 210 tok/sQwen3.6 35B-A3B · 4-bit · one user
Users
≈ 220–360at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Passive — needs server airflow

8× grouped · 8 cards in one server · PCIe · Qwen3.5 397B-A17B · ≈ 110 tok/s · ≈ 54–90

A market-specific card; NVIDIA publishes no datasheet. Figures from server-maker specifications (power is listed as 275 W and as 350 W).

Sources: 1 · 2

RTX PRO 6000 Server Edition (RTX PRO 6000D Blackwell Server Edition)
BlackwellRTX PRO 6000 Server Edition shown — same design

RTX PRO 6000D Blackwell Server Edition

84 GB GDDR7 · 1.40 TB/s

Power
600 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
122B MoE4× → 397B MoE
Typical TPS
≈ 24 tok/sJais 2 70B · FP4 · one user
Users
≈ 20–34at ≥15 tok/s each
Runs
Jais 2 70BQwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 5.0 x16Cooling: Passive — needs server airflow

4× grouped · 4 cards · PCIe · Qwen3.5 397B-A17B · ≈ 100 tok/s · ≈ 41–69

A market-specific server card (also written “RTX 6000D”); NVIDIA publishes no datasheet. Figures from server-maker specifications.

Sources: 1

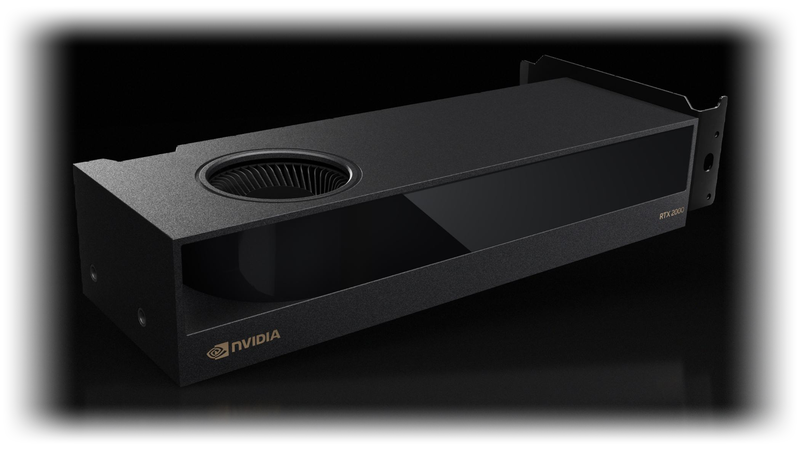
RTX PRO 4500 Blackwell Server Edition
Blackwell

RTX PRO 4500 Blackwell Server Edition

32 GB GDDR7 · 0.80 TB/s

Power
165 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
35B MoE8× → 320B MoE
Typical TPS
≈ 200 tok/sQwen3.6 35B-A3B · FP4 · one user
Users
≈ 84–140at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 5.0 x16Cooling: Passive — needs server airflow

8× grouped · 8 cards in one server · PCIe · GLM-5.3-Flash · ≈ 100 tok/s · ≈ 53–89

Single-slot and passive.

Sources: 1

L4
Ada Lovelace

L4

24 GB GDDR6 ECC · 0.30 TB/s

Power
72 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
35B MoE8× → 122B MoE
Typical TPS
≈ 77 tok/sGemma 4 26B-A4B · 4-bit · one user
Users
≈ 14–24at ≥15 tok/s each
Runs
Gemma 4 31BQwen3.8 27Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Passive — needs server airflow

8× grouped · 8 low-profile cards · PCIe · Qwen3.5 122B-A10B · ≈ 82 tok/s · ≈ 34–56

Low-profile, single-slot, 72 W — fits almost any server.

Sources: 1 · 2

L4 (L2)
Ada LovelaceL4 shown — same design

L2

24 GB GDDR6 · 0.30 TB/s

Power
—
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
35B MoE8× → 122B MoE
Typical TPS
≈ 77 tok/sGemma 4 26B-A4B · 4-bit · one user
Users
≈ 14–24at ≥15 tok/s each
Runs
Gemma 4 31BQwen3.8 27Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Passive — needs server airflow

8× grouped · 8 low-profile cards · PCIe · Qwen3.5 122B-A10B · ≈ 82 tok/s · ≈ 34–56

A market-specific card; NVIDIA publishes no datasheet or power figure. Memory confirmed by NVIDIA’s vGPU documentation; other figures from resellers.

Sources: 1

Professional workstation cards

ECC memory, certified drivers, blower and Max-Q designs that stack in a tower.

RTX PRO 6000 Blackwell Workstation Edition
Blackwell

RTX PRO 6000 Blackwell Workstation Edition

96 GB GDDR7 ECC · 1.79 TB/s

Power
600 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
122B MoE2× → 122B MoE
Typical TPS
≈ 230 tok/sgpt-oss-120b · FP4 · one user
Users
≈ 110–180at ≥15 tok/s each
Runs
Qwen3.5 122B-A10Bgpt-oss-120bMistral Small 4Jais 2 70BALLaM 7B

Interconnect: PCIe 5.0 x16Cooling: Active — flow-through

2× grouped · 2 cards · PCIe · Qwen3.5 122B-A10B · ≈ 110 tok/s · ≈ 370–620

Sources: 1

RTX PRO 6000 Blackwell Max-Q Workstation Edition
Blackwell

RTX PRO 6000 Blackwell Max-Q Workstation Edition

96 GB GDDR7 ECC · 1.79 TB/s

Power
300 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
122B MoE4× → 397B MoE
Typical TPS
≈ 230 tok/sgpt-oss-120b · FP4 · one user
Users
≈ 110–180at ≥15 tok/s each
Runs
Qwen3.5 122B-A10Bgpt-oss-120bMistral Small 4Jais 2 70BALLaM 7B

Interconnect: PCIe 5.0 x16Cooling: Active — blower

4× grouped · 4 cards in one tower · PCIe · Qwen3.5 397B-A17B · ≈ 110 tok/s · ≈ 72–120

The same chip and 96 GB as the Workstation Edition at half the power — built to stack four in one tower.

Sources: 1

RTX PRO 5000 Blackwell 72GB
Blackwell

RTX PRO 5000 Blackwell 72GB

72 GB GDDR7 ECC · 1.34 TB/s

Power
300 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
≤ 70B4× → 355B MoE
Typical TPS
≈ 23 tok/sJais 2 70B · FP4 · one user
Users
≈ 14–24at ≥15 tok/s each
Runs
Jais 2 70BQwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 5.0 x16Cooling: Active — blower

4× grouped · 4 cards in one tower · PCIe · GLM-4.7 · ≈ 73 tok/s · ≈ 15–25

Sources: 1 · 2

RTX PRO 5000 Blackwell 48GB
Blackwell

RTX PRO 5000 Blackwell 48GB

48 GB GDDR7 ECC · 1.34 TB/s

Power
300 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
≤ 70B4× → 122B MoE
Typical TPS
≈ 260 tok/sQwen3.6 35B-A3B · FP4 · one user
Users
≈ 220–360at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 5.0 x16Cooling: Active — blower

4× grouped · 4 cards in one tower · PCIe · Qwen3.5 122B-A10B · ≈ 120 tok/s · ≈ 640–1,100

Sources: 1

RTX PRO 4500 Blackwell Workstation Edition
Blackwell

RTX PRO 4500 Blackwell Workstation Edition

32 GB GDDR7 ECC · 0.90 TB/s

Power
200 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
35B MoE4× → 122B MoE
Typical TPS
≈ 210 tok/sQwen3.6 35B-A3B · FP4 · one user
Users
≈ 84–140at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 5.0 x16Cooling: Active — blower

4× grouped · 4 cards in one tower · PCIe · Qwen3.5 122B-A10B · ≈ 110 tok/s · ≈ 290–480

Sources: 1

RTX PRO 4000 Blackwell
Blackwell

RTX PRO 4000 Blackwell

24 GB GDDR7 ECC · 0.67 TB/s

Power
145 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
35B MoE4× → 122B MoE
Typical TPS
≈ 30 tok/sQwen3.8 27B · FP4 · one user
Users
≈ 37–61at ≥15 tok/s each
Runs
Gemma 4 31BQwen3.8 27Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 5.0 x16Cooling: Active fan

4× grouped · 4 single-slot cards · PCIe · Qwen3.5 122B-A10B · ≈ 91 tok/s · ≈ 61–100

Single-slot.

Sources: 1

RTX PRO 4000 Blackwell SFF Edition
Blackwell

RTX PRO 4000 Blackwell SFF Edition

24 GB GDDR7 ECC · 0.43 TB/s

Power
70 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
35B MoE
Typical TPS
≈ 20 tok/sQwen3.8 27B · FP4 · one user
Users
≈ 37–61at ≥15 tok/s each
Runs
Gemma 4 31BQwen3.8 27Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 5.0 x8Cooling: Active fan

Low-profile, 70 W, powered from the slot.

Sources: 1

RTX PRO 2000 Blackwell
Blackwell

RTX PRO 2000 Blackwell

16 GB GDDR7 ECC · 0.29 TB/s

Power
70 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
25B MoE
Typical TPS
≈ 38 tok/sQwen3.5 9B · FP4 · one user
Users
≈ 110–180at ≥15 tok/s each
Runs
Qwen3.5 9BALLaM 7B

Interconnect: PCIe 5.0 x8Cooling: Active fan

Low-profile, 70 W, powered from the slot.

Sources: 1

RTX 6000 Ada Generation
Ada Lovelace

RTX 6000 Ada Generation

48 GB GDDR6 ECC · 0.96 TB/s

Power
300 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
≤ 70B4× → 122B MoE
Typical TPS
≈ 220 tok/sQwen3.6 35B-A3B · 4-bit · one user
Users
≈ 220–360at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Active — blower

4× grouped · 4 cards in one tower · PCIe · Qwen3.5 122B-A10B · ≈ 110 tok/s · ≈ 460–770

Sources: 1

RTX 5880 Ada Generation
Ada Lovelace

RTX 5880 Ada Generation

48 GB GDDR6 ECC · 0.96 TB/s

Power
285 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
≤ 70B4× → 122B MoE
Typical TPS
≈ 220 tok/sQwen3.6 35B-A3B · 4-bit · one user
Users
≈ 220–360at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Active — blower

4× grouped · 4 cards in one tower · PCIe · Qwen3.5 122B-A10B · ≈ 110 tok/s · ≈ 460–770

Sources: 1

RTX 5000 Ada Generation
Ada Lovelace

RTX 5000 Ada Generation

32 GB GDDR6 ECC · 0.58 TB/s

Power
250 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
35B MoE4× → 122B MoE
Typical TPS
≈ 160 tok/sQwen3.6 35B-A3B · 4-bit · one user
Users
≈ 84–140at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Active — blower

4× grouped · 4 cards in one tower · PCIe · Qwen3.5 122B-A10B · ≈ 88 tok/s · ≈ 47–79

Sources: 1

RTX 4500 Ada Generation
Ada Lovelace

RTX 4500 Ada Generation

24 GB GDDR6 ECC · 0.43 TB/s

Power
210 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
35B MoE4× → 122B MoE
Typical TPS
≈ 20 tok/sQwen3.8 27B · 4-bit · one user
Users
≈ 37–61at ≥15 tok/s each
Runs
Gemma 4 31BQwen3.8 27Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Active — blower

4× grouped · 4 cards in one tower · PCIe · Qwen3.5 122B-A10B · ≈ 76 tok/s · ≈ 25–41

Sources: 1 · 2

RTX 4000 Ada Generation
Ada Lovelace

RTX 4000 Ada Generation

20 GB GDDR6 ECC · 0.36 TB/s

Power
130 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
≤ 31B4× → ≤ 70B
Typical TPS
≈ 98 tok/sgpt-oss-20b · 4-bit · one user
Users
≈ 40–68at ≥15 tok/s each
Runs
Gemma 4 26B-A4Bgpt-oss-20bQwen3.5 9BALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Active fan

4× grouped · 4 single-slot cards · PCIe · Jais 2 70B · ≈ 14 tok/s · ≈ 1

Single-slot.

Sources: 1

RTX 4000 SFF Ada Generation
Ada Lovelace

RTX 4000 SFF Ada Generation

20 GB GDDR6 ECC · 0.28 TB/s

Power
70 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
≤ 31B
Typical TPS
≈ 80 tok/sgpt-oss-20b · 4-bit · one user
Users
≈ 17–29at ≥15 tok/s each
Runs
Gemma 4 26B-A4Bgpt-oss-20bQwen3.5 9BALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Active fan

Low-profile, 70 W, powered from the slot.

Sources: 1

RTX 2000 Ada Generation
Ada Lovelace

RTX 2000 Ada Generation

16 GB GDDR6 ECC · 0.22 TB/s

Power
70 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
25B MoE
Typical TPS
≈ 30 tok/sQwen3.5 9B · 4-bit · one user
Users
≈ 46–76at ≥15 tok/s each
Runs
Qwen3.5 9BALLaM 7B

Interconnect: PCIe 4.0 x8Cooling: Active fan

Low-profile, 70 W, powered from the slot.

Sources: 1

A800 40GB Active
Ampere

A800 40GB Active

40 GB HBM2 · 1.55 TB/s

Power
240 W
Fits
RackTowerDesktop
Precision
INT8 · FP16
Model tags
35B MoE4× → 122B MoE
Typical TPS
≈ 280 tok/sQwen3.6 35B-A3B · 4-bit · one user
Users
≈ 150–250at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: NVLink bridge (pair) · 400 GB/sCooling: Active — blower

4× grouped · 4 cards in one tower · PCIe · Qwen3.5 122B-A10B · ≈ 120 tok/s · ≈ 460–770

NVIDIA’s name is “A800 40GB Active” (some resellers write RTX A800). A compute card with no display outputs.

Sources: 1 · 2
Consumer cards

Fast memory and big fans — popular for development and single-user work.

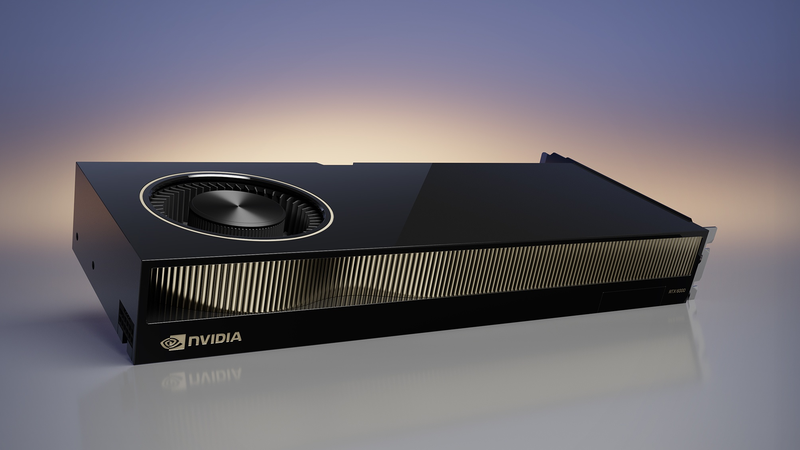
GeForce RTX 5090
Blackwell

GeForce RTX 5090

32 GB GDDR7 · 1.79 TB/s

Power
575 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
35B MoE2× → ≤ 70B
Typical TPS
≈ 300 tok/sQwen3.6 35B-A3B · FP4 · one user
Users
≈ 84–140at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 5.0 x16Cooling: Active — flow-through

2× grouped · 2 cards · PCIe · Jais 2 70B · ≈ 32 tok/s · ≈ 10–18

A consumer card: NVIDIA’s GeForce driver licence excludes data-centre deployment.

Sources: 1 · 2

GeForce RTX 4090
Ada Lovelace

GeForce RTX 4090

24 GB GDDR6X · 1.01 TB/s

Power
450 W
Fits
RackTowerDesktop
Precision
FP8 · FP16
Model tags
35B MoE2× → 35B MoE
Typical TPS
≈ 44 tok/sQwen3.8 27B · 4-bit · one user
Users
≈ 37–61at ≥15 tok/s each
Runs
Gemma 4 31BQwen3.8 27Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Active fan

2× grouped · 2 cards · PCIe · Qwen3.6 35B-A3B · ≈ 120 tok/s · ≈ 220–360

Previous-generation consumer flagship; production ended in late 2024. Same GeForce licence terms.

Sources: 1 · 2
Huawei Ascend

Inference and video-analytics cards on Huawei’s own AI silicon and software stack.

Atlas 300I A2 64GB
Ascend 910-series

Atlas 300I A2 64GB

64 GB HBM ECC · 1.60 TB/s

Power
350 W
Fits
RackTowerDesktop
Precision
INT8 · FP16
Model tags
≤ 70B4× → 320B MoE
Typical TPS
≈ 16 tok/sJais 2 70B · 4-bit · one user
Users
≈ 4–8at ≥15 tok/s each
Runs
Jais 2 70BQwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 5.0 x16Cooling: Passive — needs server airflow

4× grouped · 4 cards · PCIe · GLM-5.3-Flash · ≈ 50 tok/s · ≈ 14–22

Uses a Huawei 910-series processor — check export-control rules and local availability before planning.

Sources: 1 · 2
Atlas 300I Duo 96GB
Ascend 310P

Atlas 300I Duo 96GB

96 GB LPDDR4X ECC · 0.41 TB/s

Power
150 W
Fits
RackTowerDesktop
Precision
INT8 · FP16
Model tags
122B MoE4× → 397B MoE
Typical TPS
≈ 37 tok/sgpt-oss-120b · 4-bit · one user
Users
≈ 3–5at ≥15 tok/s each
Runs
Qwen3.5 122B-A10Bgpt-oss-120bMistral Small 4Jais 2 70BALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Passive — needs server airflow

4× grouped · 4 cards · PCIe · Qwen3.5 397B-A17B · ≈ 24 tok/s · ≈ 1–2

Two processors with 48 GB each — larger models are split across both. Inference only.

Sources: 1 · 2
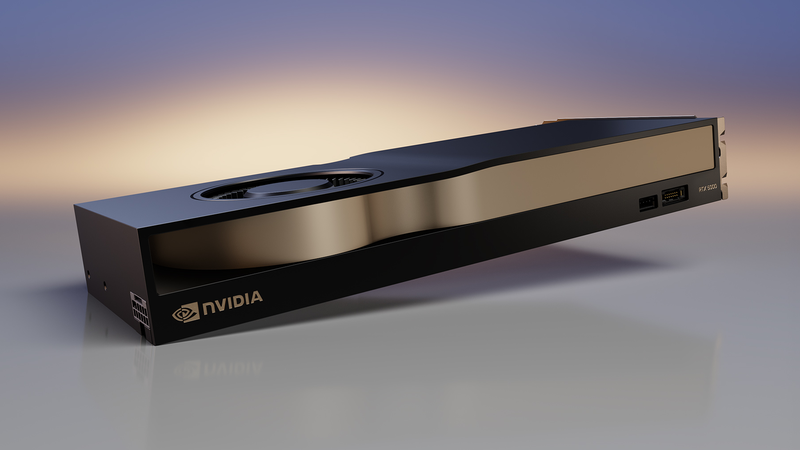
Atlas 300I Pro (Atlas 300V Pro 48GB)
Ascend 310PAtlas 300I Pro shown — same design

Atlas 300V Pro 48GB

48 GB LPDDR4X ECC · 0.20 TB/s

Power
72 W
Fits
RackTowerDesktop
Precision
INT8 · FP16
Model tags
≤ 70B
Typical TPS
≈ 36 tok/sQwen3.6 35B-A3B · 4-bit · one user
Users
≈ 5–9at ≥15 tok/s each
Runs
Qwen3.6 35B-A3BGemma 4 31Bgpt-oss-20bALLaM 7B

Interconnect: PCIe 4.0 x16Cooling: Passive — needs server airflow

A video-analytics card (128 channels of 1080p decode); also sold with 24 GB.

Sources: 1 · 2
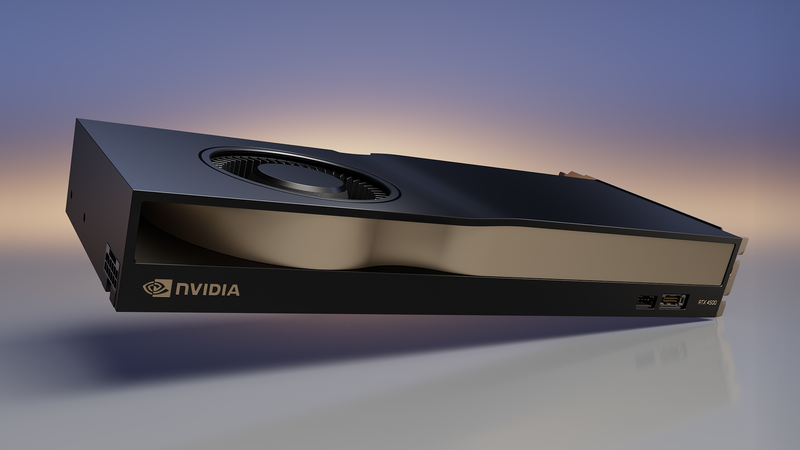
Desktop AI systems

Self-contained boxes with large unified memory — quiet, compact, single-desk.

DGX Spark (GB10)
Grace Blackwell

DGX Spark (GB10)

128 GB LPDDR5x unified · 0.27 TB/s

Power
240 W
Fits
RackTowerDesktop
Precision
FP4 · FP8 · FP16
Model tags
122B MoE2× → 320B MoE
Typical TPS
≈ 50 tok/sgpt-oss-120b · FP4 · one user
Users
≈ 4–6at ≥15 tok/s each
Runs
Qwen3.5 122B-A10Bgpt-oss-120bMistral Small 4Jais 2 70BALLaM 7B

Interconnect: ConnectX-7 · 2× 200 Gb/sCooling: Built-in fans

2× grouped · 2 units · 200 Gb/s link · GLM-5.3-Flash · ≈ 16 tok/s · ≈ 1–2

240 W is the power supply; the chip is 140 W. Also sold by system makers under their own names. Up to four units can be linked.

Sources: 1 · 2
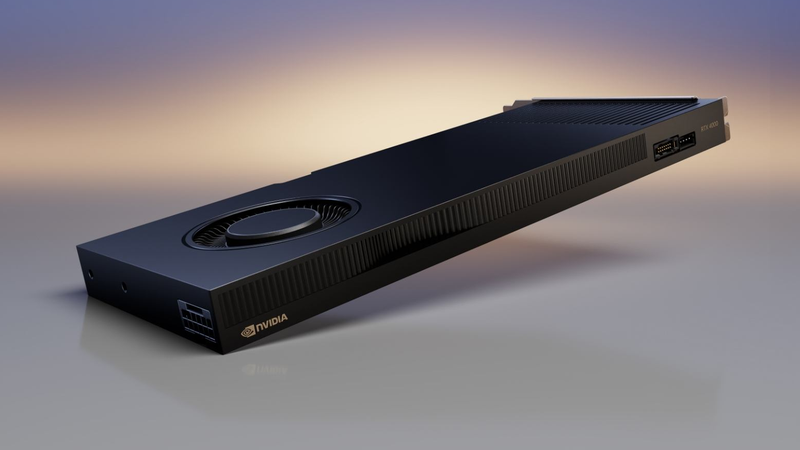
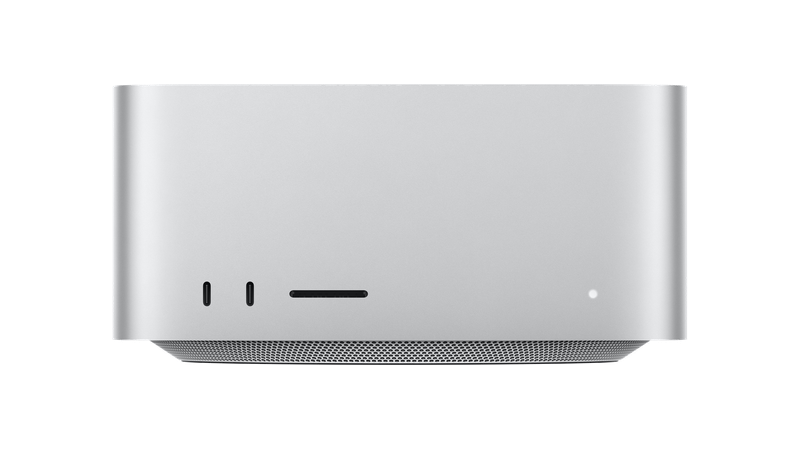
Mac Studio · M5 Max · 128GB
Apple M5 Max

Mac Studio · M5 Max · 128GB

128 GB unified · 0.61 TB/s

Power
480 W
Fits
RackTowerDesktop
Precision
4-bit · 8-bit · BF16
Model tags
122B MoE
Typical TPS
≈ 45 tok/sQwen3.5 122B-A10B · 4-bit · one user
Users
≈ 8–14at ≥15 tok/s each
Runs
Qwen3.5 122B-A10Bgpt-oss-120bMistral Small 4Jais 2 70BALLaM 7B

Interconnect: Thunderbolt 5 (RDMA)Cooling: Built-in fans

Mac Studio (2026). 480 W is Apple’s maximum continuous system power; Apple publishes no AI TOPS figure.

Sources: 1 · 2
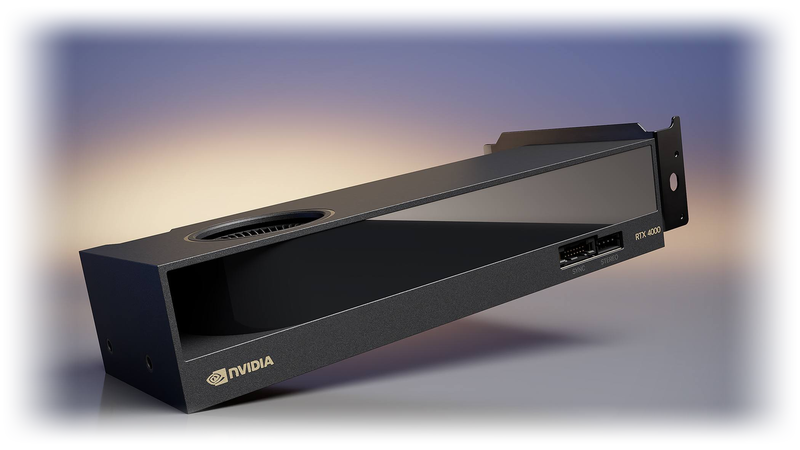
Mac Studio · M5 Ultra · 256GB
Apple M5 Ultra

Mac Studio · M5 Ultra · 256GB

256 GB unified · 1.20 TB/s

Power
480 W
Fits
RackTowerDesktop
Precision
4-bit · 8-bit · BF16
Model tags
397B MoE
Typical TPS
≈ 66 tok/sQwen3.5 122B-A10B · 4-bit · one user
Users
≈ 22–38at ≥15 tok/s each
Runs
GLM-5.3-FlashDeepSeek-V4-FlashQwen3.5 122B-A10Bgpt-oss-120bALLaM 7B

Interconnect: Thunderbolt 5 (RDMA)Cooling: Built-in fans

Also offered with 512 GB. Several Macs can be joined over Thunderbolt 5 to serve one larger model.

Sources: 1 · 2
Grouped

What a group of them holds.

Large models are served across several devices at once (tensor parallel): memory and bandwidth add up. NVLink scales better than plain PCIe. Each row is the largest popular model that fits the group with room for 8K-token conversations.

ConfigurationTotal memoryLargest model it holdsTypical TPS (one user)Users at ≥15 tok/s
8× B300 (Blackwell Ultra) 8-GPU baseboard · NVLink2,304 GBKimi K2.6 · FP4≈ 200 tok/s≈ 3,100–5,100
8× B200 8-GPU baseboard · NVLink1,440 GBKimi K2.6 · FP4≈ 200 tok/s≈ 1,900–3,200
8× H200 SXM 8-GPU baseboard · NVLink1,128 GBKimi K2.6 · FP8≈ 190 tok/s≈ 1,200–2,000
8× H100 SXM 8-GPU baseboard · NVLink640 GBQwen3.5 397B-A17B · FP8≈ 180 tok/s≈ 820–1,400
4× H200 NVL 4-way NVLink bridge564 GBQwen3.5 397B-A17B · FP8≈ 170 tok/s≈ 510–840
4× RTX PRO 6000 Blackwell Max-Q Workstation Edition 4 cards in one tower · PCIe384 GBQwen3.5 397B-A17B · FP4≈ 110 tok/s≈ 72–120
8× L40S 8 cards in one server · PCIe384 GBQwen3.5 397B-A17B · 4-bit≈ 110 tok/s≈ 54–90
8× L4 8 low-profile cards · PCIe192 GBQwen3.5 122B-A10B · 4-bit≈ 82 tok/s≈ 34–56
2× GeForce RTX 5090 2 cards · PCIe64 GBJais 2 70B · FP4≈ 32 tok/s≈ 10–18
2× DGX Spark (GB10) 2 units · 200 Gb/s link256 GBGLM-5.3-Flash · FP4≈ 16 tok/s≈ 1–2
Rack server vs tower server

Where the hardware lives changes what you can put in it.

The same model can run in either. What differs is airflow, noise, power, density and how far it scales.

Rack server
Tower server
Rack serverTower server
Form1U–8U chassis in a 19-inch rack, stacked with networking and storage.Stand-alone pedestal; many convert to a 4U–5U rack chassis.
Where it livesA data room or colocation hall with cooling, redundant power and physical security.An office, lab or branch — a standard floor and wall socket.
AcceleratorsUp to 8 SXM modules on a baseboard, or 4–10 passive PCIe cards.Typically 1–4 actively cooled workstation cards (blower or Max-Q cards stack best).
CoolingHigh-pressure front-to-back airflow, or direct liquid cooling; passive server cards rely on it.Each card cools itself; quieter and tolerant of an ordinary room.
PowerRoughly 2–4 kW for a 4-GPU PCIe server, 10–15 kW for an 8-GPU baseboard system.Roughly 1–2 kW, on standard office power.
NoiseLoud — built for unattended rooms.Office-friendly.
OperationsRedundant power supplies, out-of-band management, hot-swap drives, remote rebuild.Simpler, hands-on; fewer redundant parts.
Scales toMany servers joined by 400–800 Gb/s networking — hundreds of GPUs.One box — a team or a department.
Best forProduction serving for hundreds or thousands of users; frontier-size models.Pilots, development teams, departments and sites without a server room.

Cards built for racks: SXM modules and passive server cards (H200 NVL, L40S, RTX PRO 4500 Server Edition, L4). Cards built for towers: actively cooled workstation cards (RTX PRO 6000 Max-Q, RTX PRO 5000, RTX 6000 Ada). Blower and Max-Q cards also run in rack-mounted workstations.

Choosing by need

Start from the people, not the part.

A pilot or a small team

A single 48–96 GB card in a workstation, or a compact AI desktop.

gpt-oss-120b · Qwen3.8 27B · ALLaM 7B

A department

Four 96 GB cards in one tower or a 4–8 card PCIe rack server.

Qwen3.5 122B-A10B · GLM-5.3-Flash (4-bit) · Jais 2 70B

A whole organisation

Rack servers with 8 HBM accelerators each, scaled out over fast networking.

DeepSeek-V4-Pro · GLM-5.2 · Kimi K2.6

Branches, video and the edge

Low-profile cards at 70–75 W that fit almost any server.

Qwen3.5 9B · gpt-oss-20b · vision models
How we estimate

A stated model, not a benchmark.

Answering one token at a time is limited by memory bandwidth: each new token reads the model’s active weights once, plus every user’s conversation cache. A step takes the longer of that memory time and the arithmetic time (a roofline model).

Typical TPS = tokens per second for one user. Users = the largest number of simultaneous users that still get ≥15 tokens/s each AND whose 8K-token caches fit next to the weights, on a modern batching server (vLLM, SGLang, TensorRT-LLM).

We count 90% of memory as usable, 55–70% of peak bandwidth as achievable (higher on data-centre stacks), and mixture-of-experts models read more of their experts as the batch grows. Grouped devices add memory and bandwidth, discounted for NVLink or PCIe.

Real figures move by ±25% with the software stack, context length, prompt length and settings. Specifications are from each vendor’s datasheet (sources below); where a vendor publishes none, the card says so.

Checked against published measurements

The same model, re-run for setups that reviewers and vendors have measured. One user, decode speed.

SetupMeasuredOur estimate
RTX PRO 6000 · gpt-oss-120b196–208 tok/s≈ 230 tok/sSource
RTX 5090 · Qwen3 32B 4-bit59 tok/s≈ 62 tok/sSource
RTX 4090 · Qwen3 32B 4-bit43 tok/s≈ 36 tok/sSource
H200 · Llama 3.3 70B FP851 tok/s≈ 49 tok/sSource
2× H100 · Llama 3.3 70B FP853 tok/s≈ 51 tok/sSource
DGX Spark · gpt-oss-120b50–59 tok/s≈ 50 tok/sSource
DGX Spark · Llama 70B 4-bit4.7 tok/s≈ 4 tok/sSource
2× DGX Spark · Qwen3 235B FP411.7 tok/s≈ 13 tok/sSource
Mac Studio M3 Ultra · Llama 70B 4-bit14 tok/s≈ 13 tok/sSource
Mac Studio M3 Ultra · gpt-oss-120b78 tok/s≈ 74 tok/sSource

Running open models on your own hardware?

The Sigmix Workspace runs on every class above — from one workstation card to a rack of HBM accelerators.