By product
Sovereign AI Workspace17 tools, one login · try free Sigmix OneFree on-device AI app · iPhone Sigmix InferenceOpenAI-compatible API · in-Kingdom route Sovereign AI ServersSealed on-prem appliance Sigmix Guard™Scrubbing & audit · optional PCIe card Sigmix ZeroSovereign Windows 11 endpoint StocksIQThe AI analyst for the Saudi market Sigmix GrowthPilotCross-platform CAC & budget AI Muraqaba AISeparate product · video AI Sigmix RedPathHosted AI software you deploy · newBy industry
Banking & FinanceAligned to SAMA CSF · on-prem Public SectorAligned to NCA ECC-2:2024 · sealed HealthcarePDPL · sealed desktops EducationLighter, adaptive tone EnterpriseCustomer-facing suite · CRMHardware
AI hardware guideGPUs & accelerators · what runs what Rack vs towerWhere AI servers liveSigmix Guard™
Our scrubbing & audit layer, running Sigmix-authored firmware — with an optional PCIe card for the appliance.
Explore Sigmix Guard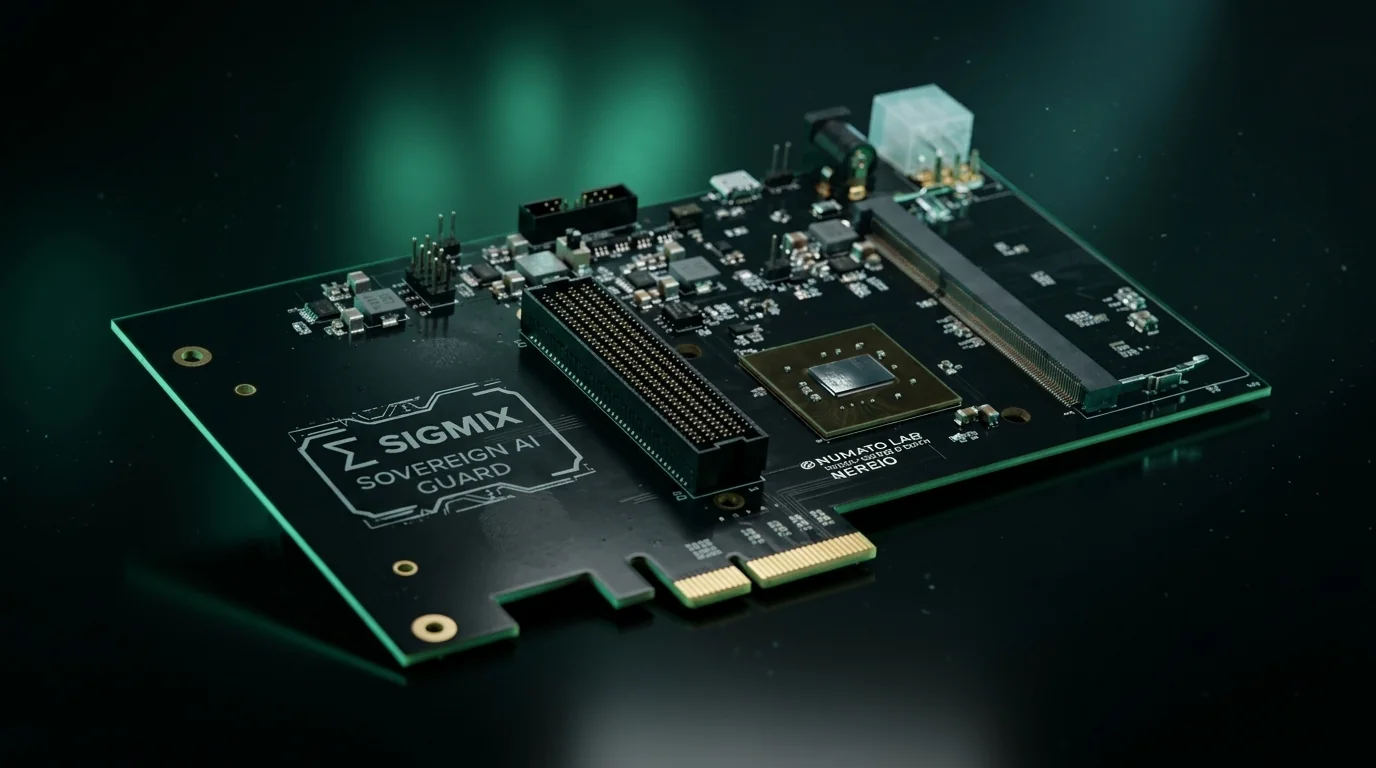
Sovereignty & compliance
Security postureAligned to NCA ECC-2:2024 · SAMA CSF · PDPL · ZATCA Zero-egress architectureDefault-deny · canary-monitored Sigmix Guard™Independent enforcement layerFor developers
Workspace APIThe Gen-AI tools, from your own code Trust CenterAudit evidence & compliance mapping0 bytes egress — nothing leaves
Every request served on-box, sealed from the internet. KSA Cloud runs elastic and in-Kingdom.
See your postureThe API, on both routes.
Everything here applies to both routes. Each route's own page has its models, prices and samples.
https://inference.sigmix.sa/ksa-sovereign-route-only/v1Authentication
Bearer keys
Send the key as Authorization: Bearer, followed by the key. x-api-key is accepted too, for SDKs that send it.
One route per key
Sovereign keys start sgx-ksa-, international keys sgx-intl-. A key on the other route's path is refused with wrong_route.
Shown once
We keep a fingerprint of each key, never the key. Revocation takes effect on the next request.
Authorization: Bearer sgx-ksa-…      # sovereign key
Authorization: Bearer sgx-intl-…     # international key
OpenAI compatibility
Request and response shapes follow OpenAI's, so the official SDKs work by changing base_url and api_key.
Endpoints
chat/completions, embeddings, audio/speech, audio/transcriptions, audio/translations, images/generations, and GET models.
Response headers
x-request-id on every response; x-sigmix-route; x-sigmix-charge-usd with the exact charge on non-streamed responses (a stream's charge is on the Usage page); x-sigmix-max-tokens-clamped when max_tokens was above the model's limit.
Model ids
Use the id from the route's model list or GET <base>/models. The same id can exist on both routes as two separate models with two prices.
Not supported yet
The Responses and Assistants APIs, file uploads and fine-tuning. Image URLs in chat work where the model fetches them; on some international models only base64 data URLs are accepted.
Chat parameters
temperature, top_p, n, stop, seed, frequency_penalty, presence_penalty, logit_bias, logprobs, top_logprobs, response_format, tools (function tools only), tool_choice, parallel_tool_calls and stream_options; reasoning_effort, reasoning_format and include_reasoning on models that reason. user, metadata, store and service_tier are accepted and not passed on. Any other parameter, or one the model cannot honour, is refused with invalid_request naming it — never silently dropped. seed is best effort. Tool-call ids are issued by us, in the call_ form.
Streaming
stream: true on chat completions returns server-sent events in OpenAI's chunk format, ending with data: [DONE].
- A stream is refused below the streaming balance floor, shown on the pricing page. Requests without
streamwork at any balance that covers them. - The most a stream could cost — its
max_tokens— is reserved before the first token.max_tokensis always sent to the model, so the ceiling holds. - Close the connection and generation stops; you are charged for what was generated, not for the ceiling.
- Send
stream_options.include_usageto receive the usage chunk; billing uses it either way.
Errors
Errors use OpenAI's shape, with a code that says whose problem it is. Nothing is charged for a request that failed.
{
  "error": {
    "message": "Your available balance does not cover this request…",
    "type": "insufficient_quota",
    "code": "insufficient_credit",
    "param": null,
    "request_id": "6f0c…"
  }
}| HTTP | Code | Whose | Meaning | What to do |
|---|---|---|---|---|
401 | invalid_api_key | Yours | The key is missing, malformed, unknown or revoked. | Send Authorization: Bearer with a current key from the console. |
403 | wrong_route | Yours | The key belongs to the other route. | Use the key on its own base path, or create a key for this route. |
403 | account_suspended | Yours | The account is suspended or closed. | |
400 | invalid_request | Yours | The body is malformed or a field is invalid. | Read error.param and error.message. |
404 | unknown_endpoint | Yours | There is no endpoint at that path. | Check the path against the endpoints table on the route page. |
404 | model_not_found | Yours | That model is not published on this route. | GET <base>/models lists what is. |
403 | model_not_allowed | Yours | The key is restricted to other models. | Edit the key's allowed models. |
400 | modality_mismatch | Yours | The model is called on a different endpoint. | Use the endpoint named in the message. |
413 | payload_too_large | Yours | The body is over 16 MB, or the audio over 25 MB. | Send less, or split the audio. |
400 | context_length_exceeded | Yours | The messages are far longer than the model's context window could hold. Refused before anything is held or sent; not charged. | Shorten the conversation, or use a model with a larger context window. |
402 | insufficient_credit | Yours | Your available balance does not cover the most this request could cost. | Add credit, or lower max_tokens. |
402 | paid_credit_required | Yours | Free-trial credit cannot pay for this model, and your paid balance does not cover the most this request could cost. | Top up, or use a model included in the free trial. |
403 | streaming_not_allowed | Yours | Streaming is off for this key or account, or the balance is under the floor. | Send without stream: true, or add credit. |
429 | rate_limited | Yours | Too many requests this minute for this key. | Wait for Retry-After seconds. |
429 | concurrency_limit | Yours | Too many requests at once for this key, or more than four requests over 1 MB still uploading at once from your account. | Wait for one to finish, or raise the key's limit. |
429 | spend_cap_reached | Yours | A daily, monthly or per-request cap you set has been reached. | Raise the cap on the key, or wait for the window. |
503 | gateway_disabled | Paused | The operator has paused the API. | Retry after Retry-After seconds; see the status page. |
503 | route_disabled | Paused | The operator has paused this route. | Retry later. A sovereign request is not moved to the other route. |
503 | modality_disabled | Paused | The operator has paused this endpoint. | Retry later. |
503 | model_disabled | Paused | The operator has paused this model. | Retry later, or use another model. |
503 | capacity_exhausted | Ours | Every endpoint for this model is busy, or the API is receiving too many large requests at once. | Retry after a moment. |
503 | upstream_unavailable | Ours | No endpoint on this route can serve the model right now. | Retry; see the status page. |
504 | upstream_timeout | Ours | The model did not answer in time. | Retry, or lower max_tokens. |
502 | upstream_error | Ours | The model endpoint failed. | Retry. Not charged. |
400 | upstream_rejected | Yours | The model refused the request — too long, or a value it does not accept. The reason is given in our words, with the parameter when there is one. | Read the message; shorten or adjust the request. |
504 | deadline_exceeded | Yours | The request reached the 15-minute limit. A streamed answer stops there and only what was generated is charged; a request that had not started answering is not charged. | Lower max_tokens, or split the work. |
503 | service_restarting | Ours | The API was restarting. A streamed answer in progress stops and only what was generated is charged; a request that had not started is not charged. | Retry after Retry-After. |
500 | internal_error | Ours | Something failed on our side. | Retry, and quote request_id if it persists. Not charged. |
Limits
Rate
Requests per minute per key: the platform default unless you set your own on the key. Exceeding it returns 429 with Retry-After.
Size
JSON bodies up to 16 MB; audio up to 25 MB; up to 8 choices (n) per chat request and 10 images per image request.
Retries
If an endpoint fails before answering, the gateway retries on another endpoint on the same route. Retry yourself on 429, 503 and 504; never on 4xx.
What we keep
For each request: when, which key, which model and route, the token, character, second or image counts, the charge, the latency and the outcome. Never the prompt, the completion, the audio or the image.
On the international route, the service that answers a request processes it under its own terms.
Ready to call it?
Create an account, make a key for the route you need, and paste a sample from its page.